A dataset gate that names the records responsible for content and incident leakage.
Python 3.10+; lists, sets, dictionaries, Unicode normalization and hash functions. The core uses standard libraries. The grader checks your selected workspace; it never fills in missing behavior from the reference.
Build and run your version
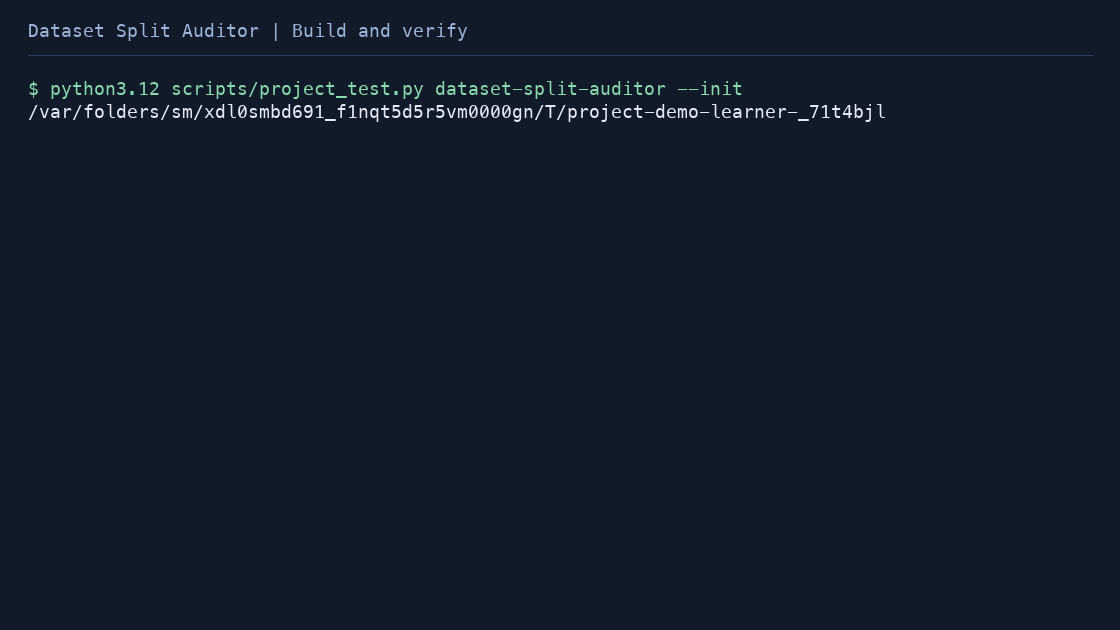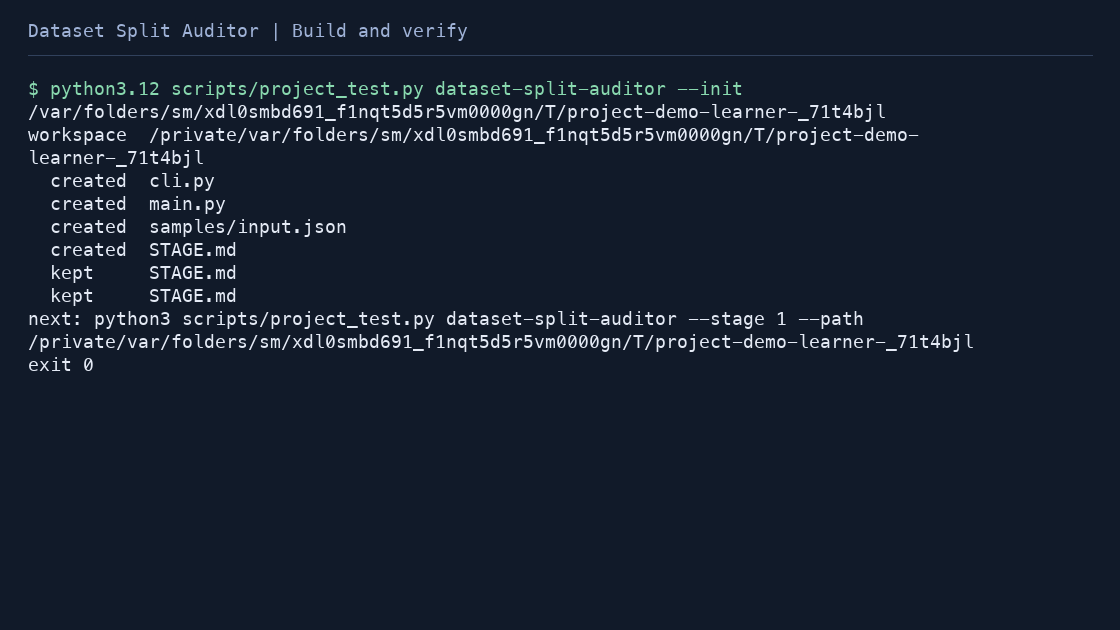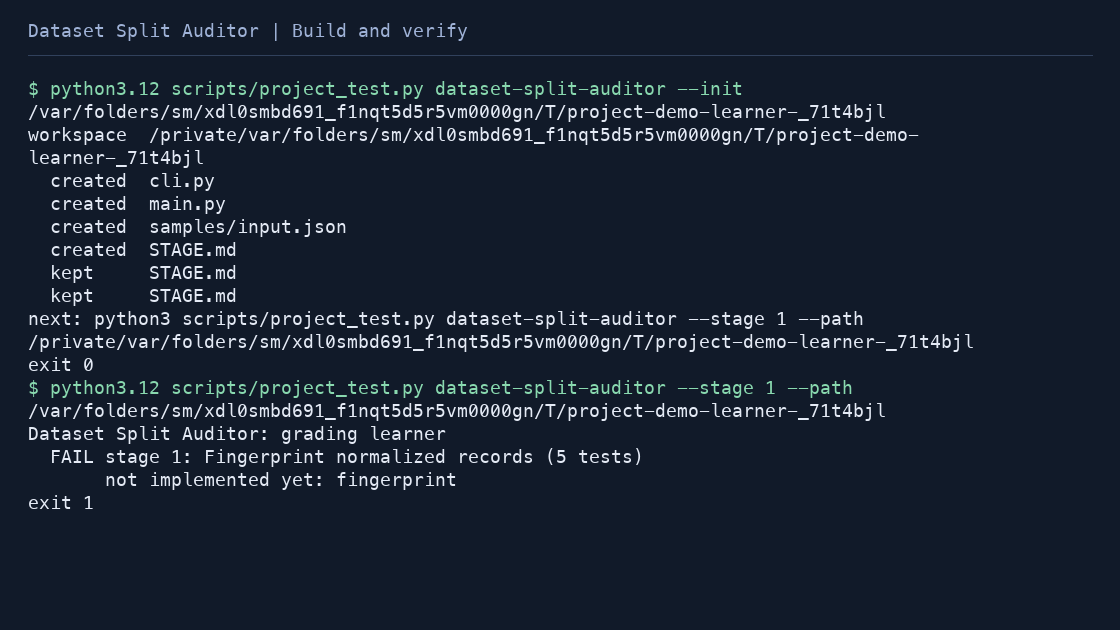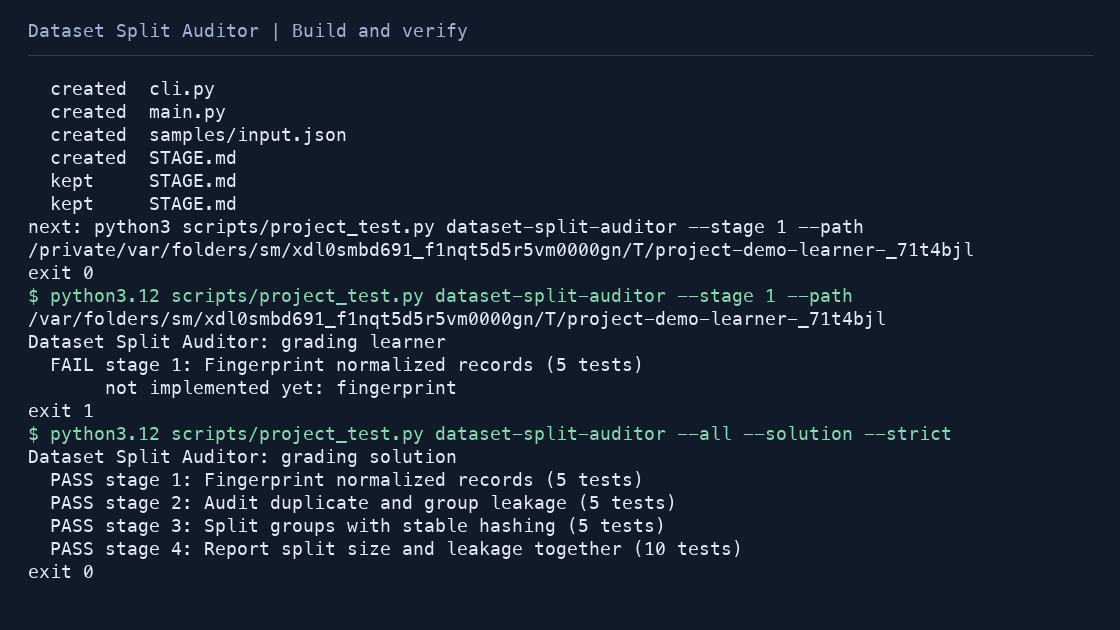
From the repository root, initialize once. A fresh starter fails intentionally.
python3 scripts/project_test.py dataset-split-auditor --init learning-artifacts/dataset-split-auditor
python3 scripts/project_test.py dataset-split-auditor --stage 1 --path learning-artifacts/dataset-split-auditor --strict
Implement each stage, then run the cumulative grader and the supplied input driver:
python3 scripts/project_test.py dataset-split-auditor --all --path learning-artifacts/dataset-split-auditor --strict
cd learning-artifacts/dataset-split-auditor
python3 cli.py samples/input.json --output split-audit.json --html split-audit.html
The driver and offline samples are provided scaffolding. Its imports resolve to your implementation. Public input types and function signatures live in the starter and API contract.
Inspect the reference separately
From the repository root:
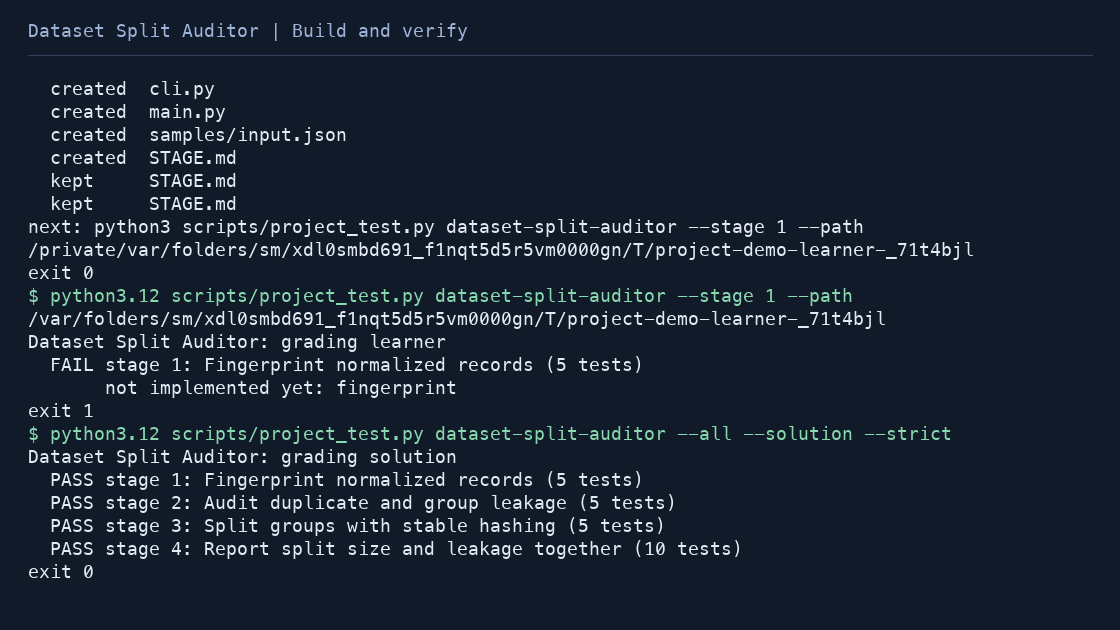
python3 scripts/project_test.py dataset-split-auditor --all --solution --strict
cd projects/dataset-split-auditor/solution
python3 cli.py samples/input.json --output split-audit.json --html split-audit.html
Observe the change
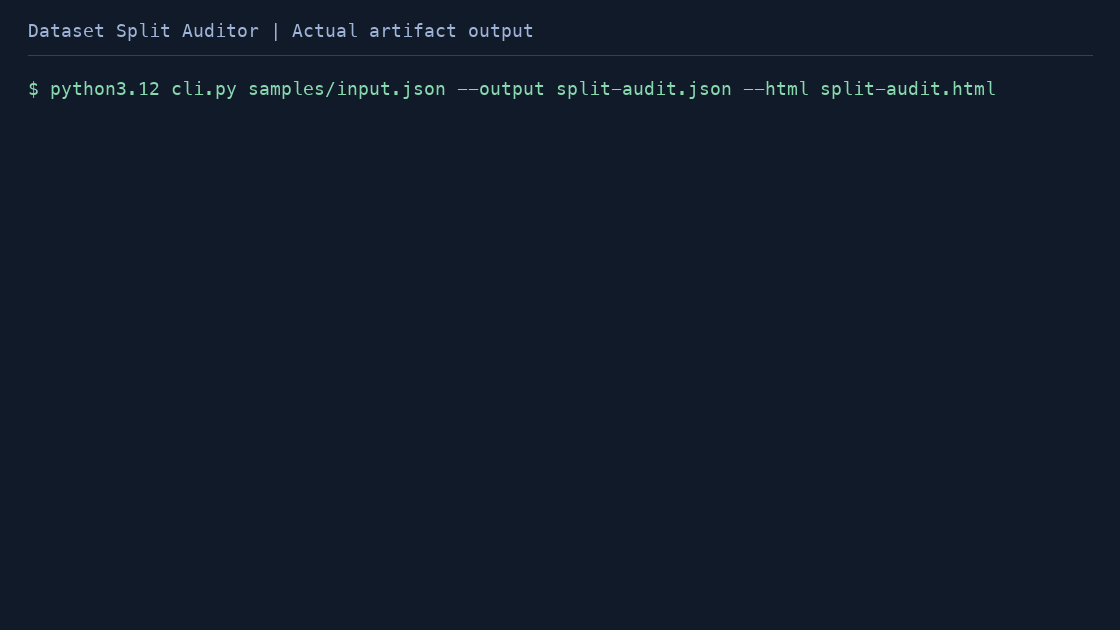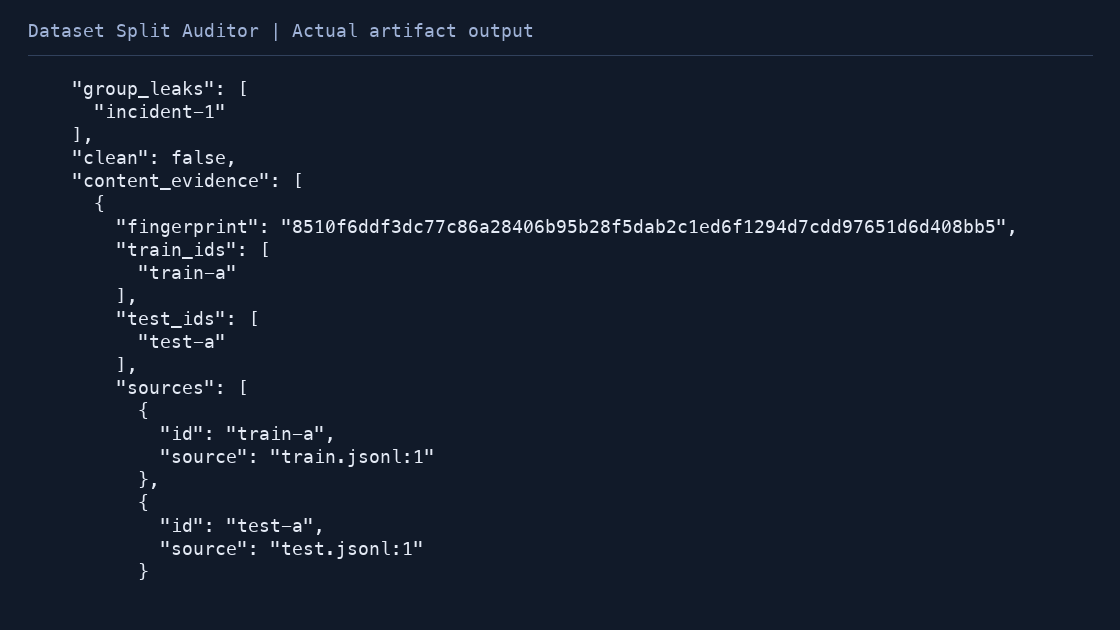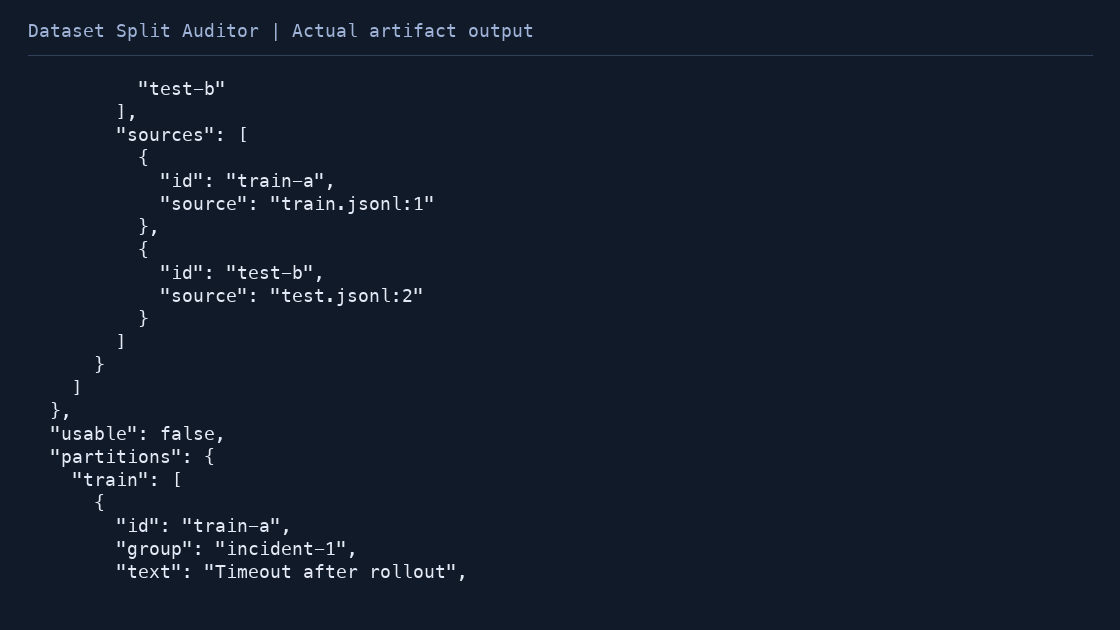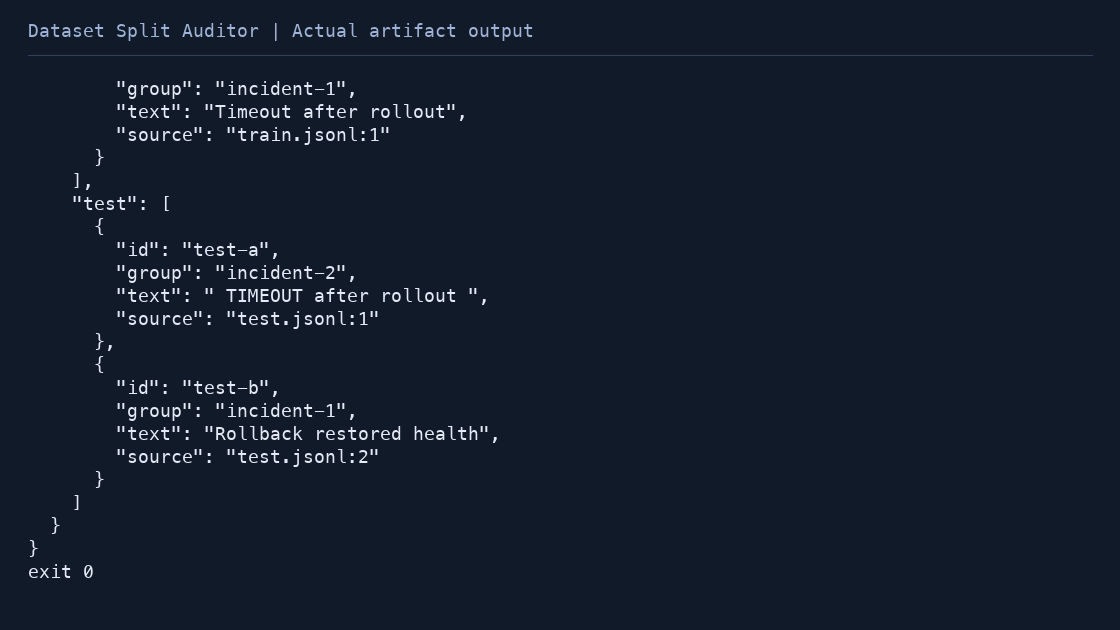
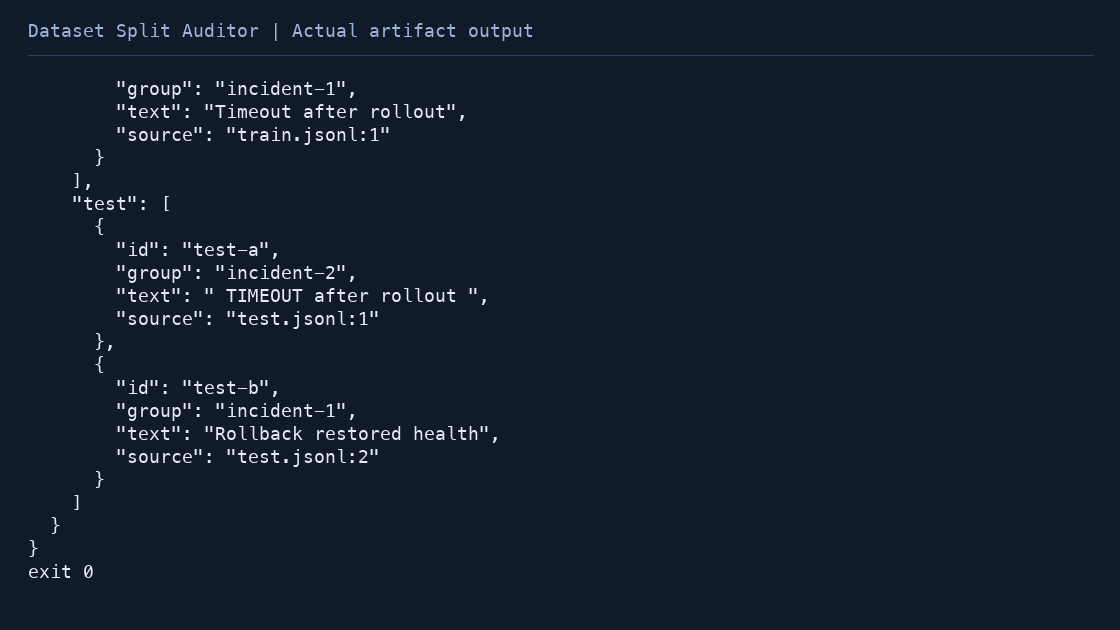
The dirty sample identifies train-a and test-a as the normalized-content overlap, then identifies train-a and test-b as the shared incident. Its usable flag is false.
Edit a copy of the sample and rerun the command. Keep the input beside the output so someone else can reproduce the result; the supplied samples are authored teaching data.
Integration and limits
Pass {train,test} records to the CLI, or {records} with --split 0.25 --seed experiment-1. Add --check in CI to return exit 2 when the split is unusable.
Normalization finds exact normalized copies, not paraphrases. Stable group hashing does not guarantee balanced classes or time-aware evaluation. Source text remains present in exported partitions.
Stages
- Fingerprint normalized records
- Audit duplicate and group leakage
- Split groups with stable hashing
- Report split size and leakage together
Primary references
Join the evaluation workflow
JSONL input is available as python3 cli.py --train train.jsonl --test test.jsonl --check --output split-audit.json. Each row requires id, group and text; extra label and source fields survive in partitions.train/partitions.test. Collision evidence includes paired record ids and any source locators supplied.
The Local Model Evaluation Harness accepts --dataset-audit split-audit.json. It requires a usable schema_version1 receipt and exact agreement between label ids and the audited test partition. A clean split is necessary evidence, not proof that the evaluation labels are good.