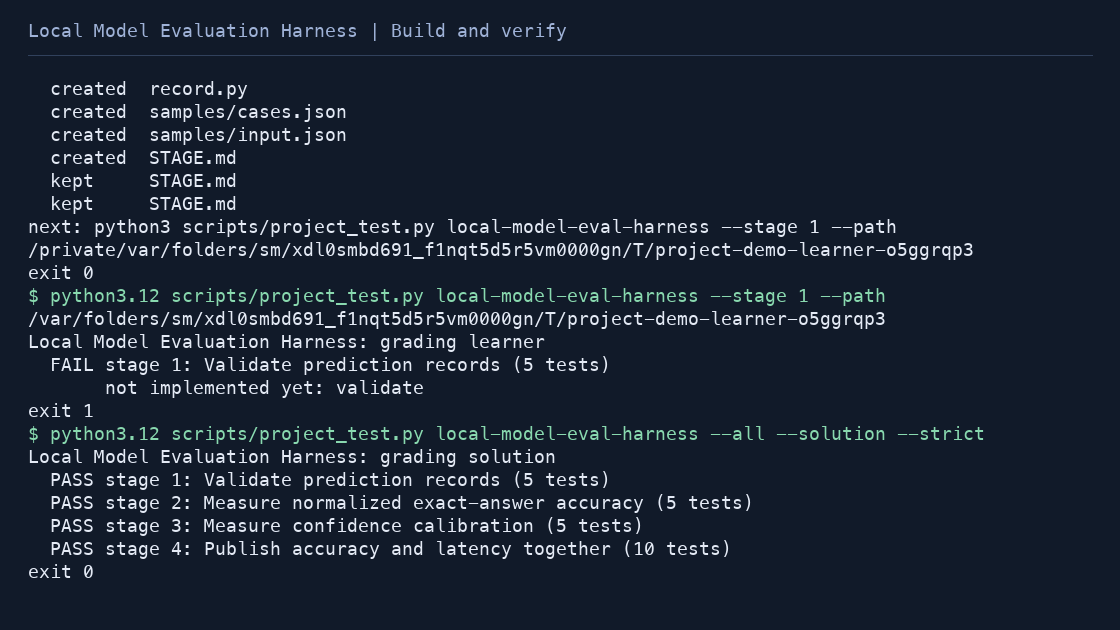
A reproducible local-model recording and comparison artifact with visible coverage and confidence error.
Python 3.10+; JSON, ratios, sorting, percentiles and basic HTTP. A live recorder additionally needs an already-running loopback OpenAI-compatible model server. The core uses standard libraries. The grader checks your selected workspace; it never fills in missing behavior from the reference.
Build and run your version
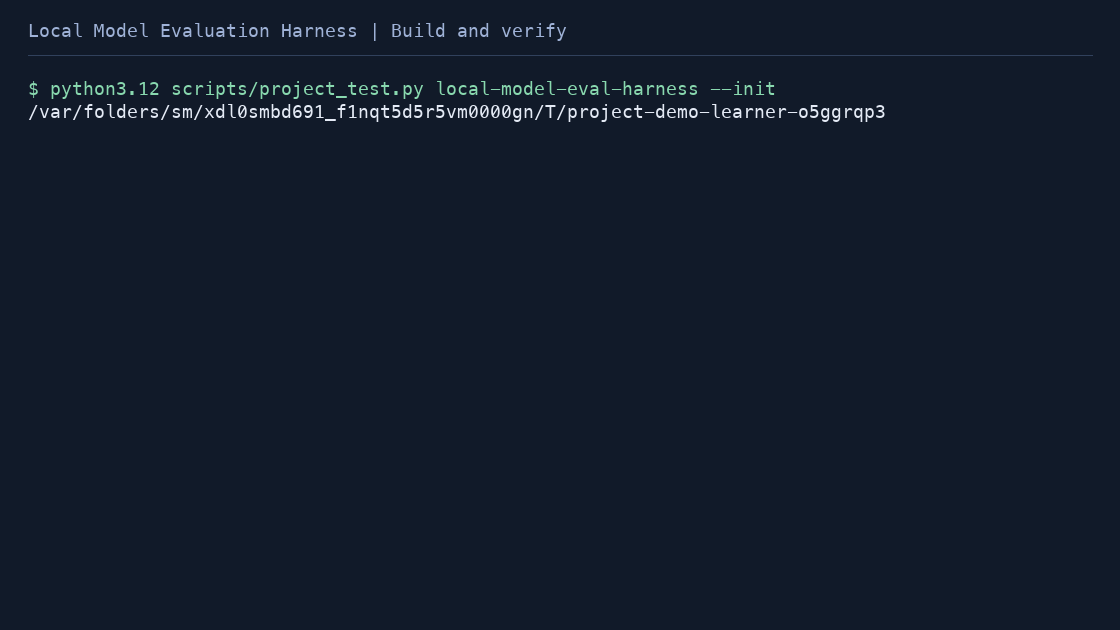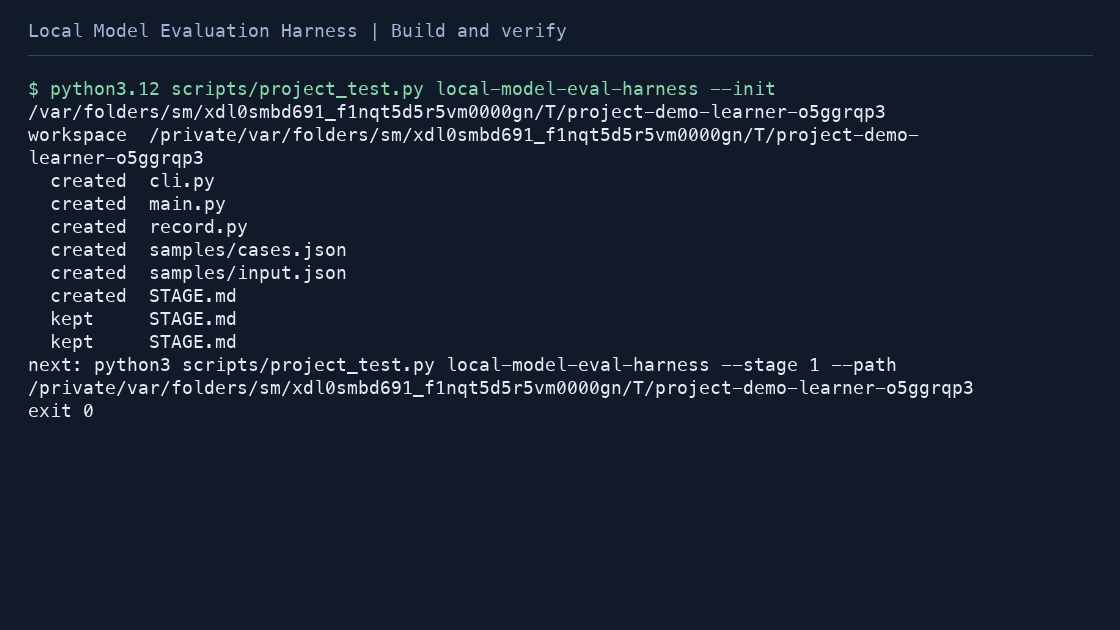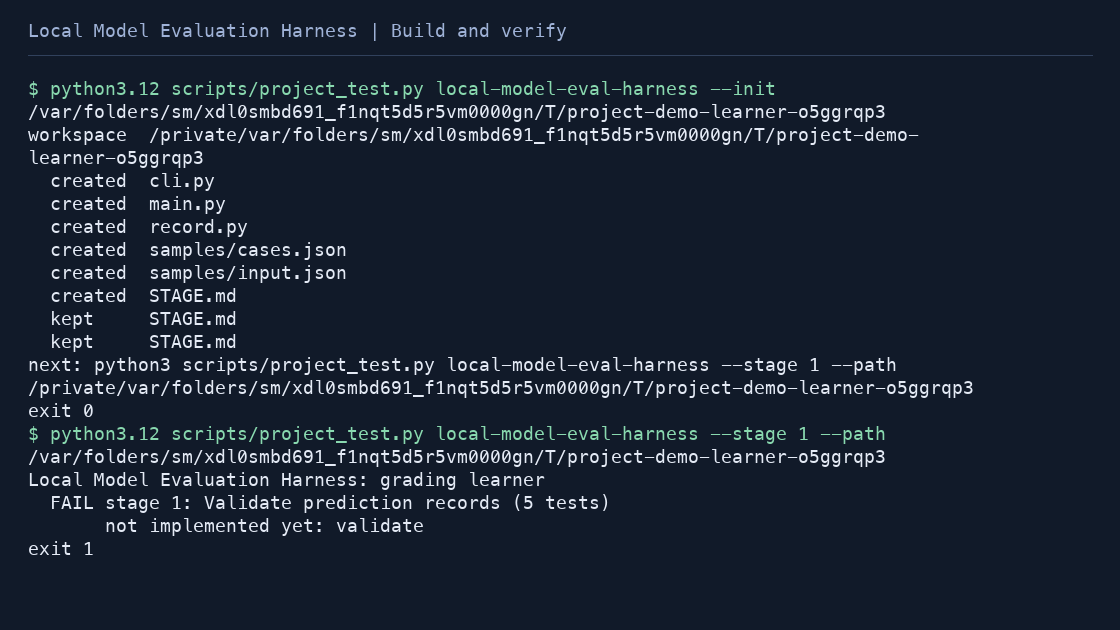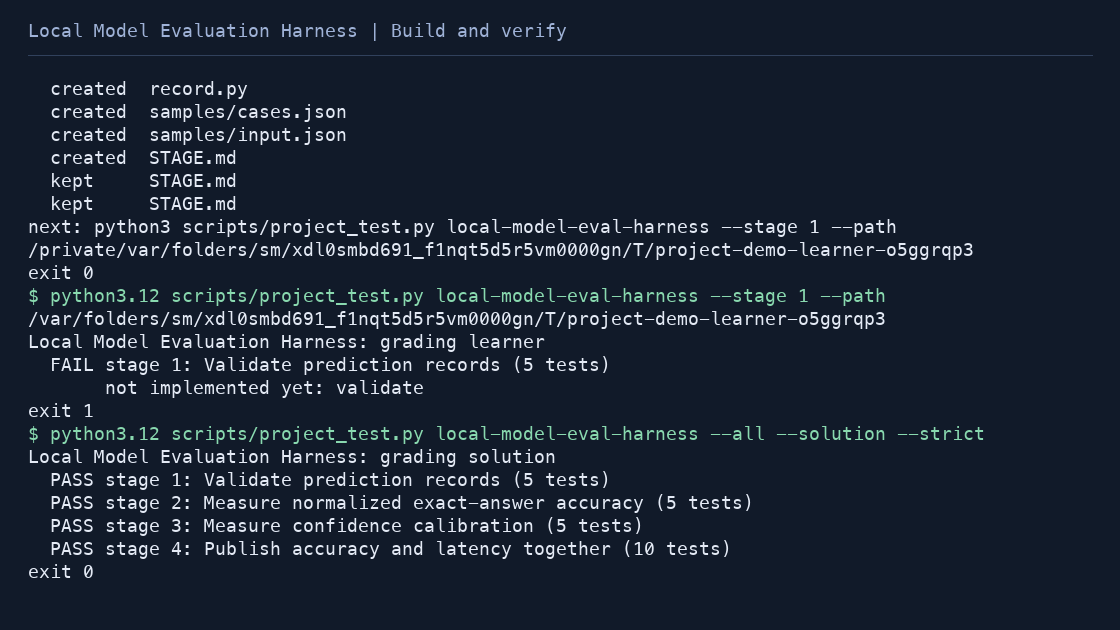
From the repository root, initialize once. A fresh starter fails intentionally.
python3 scripts/project_test.py local-model-eval-harness --init learning-artifacts/local-model-eval-harness
python3 scripts/project_test.py local-model-eval-harness --stage 1 --path learning-artifacts/local-model-eval-harness --strict
Implement each stage, then run the cumulative grader and the supplied input driver:
python3 scripts/project_test.py local-model-eval-harness --all --path learning-artifacts/local-model-eval-harness --strict
cd learning-artifacts/local-model-eval-harness
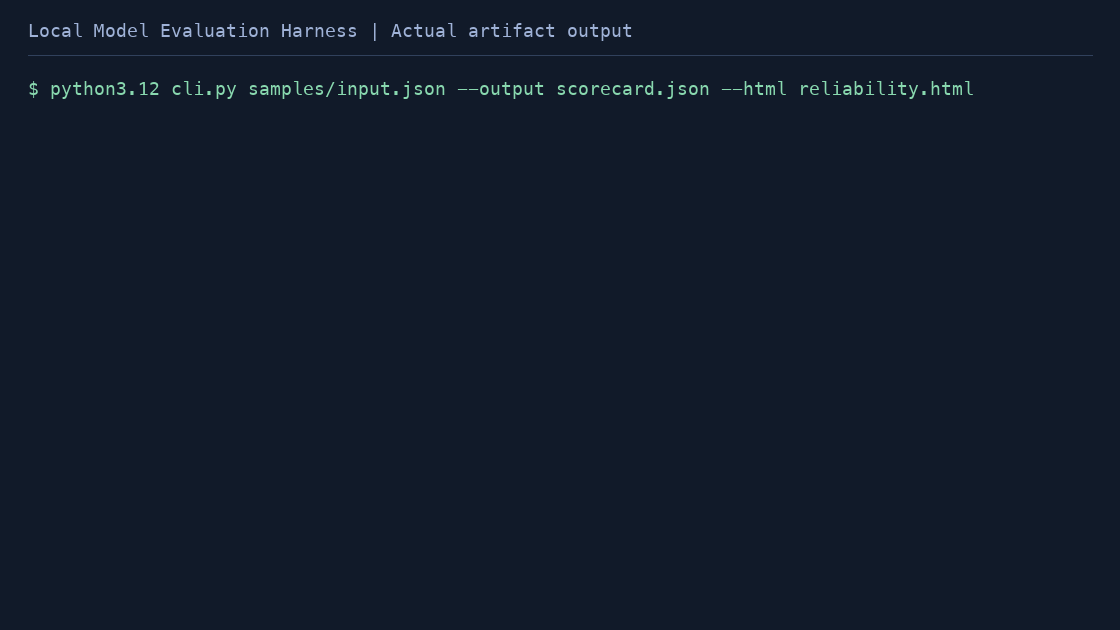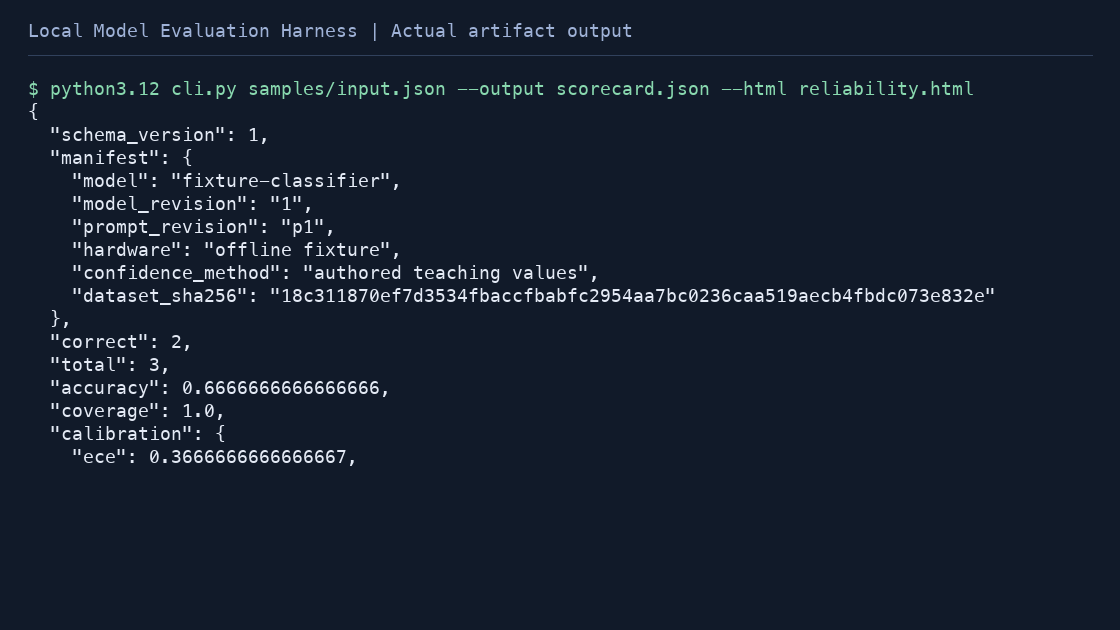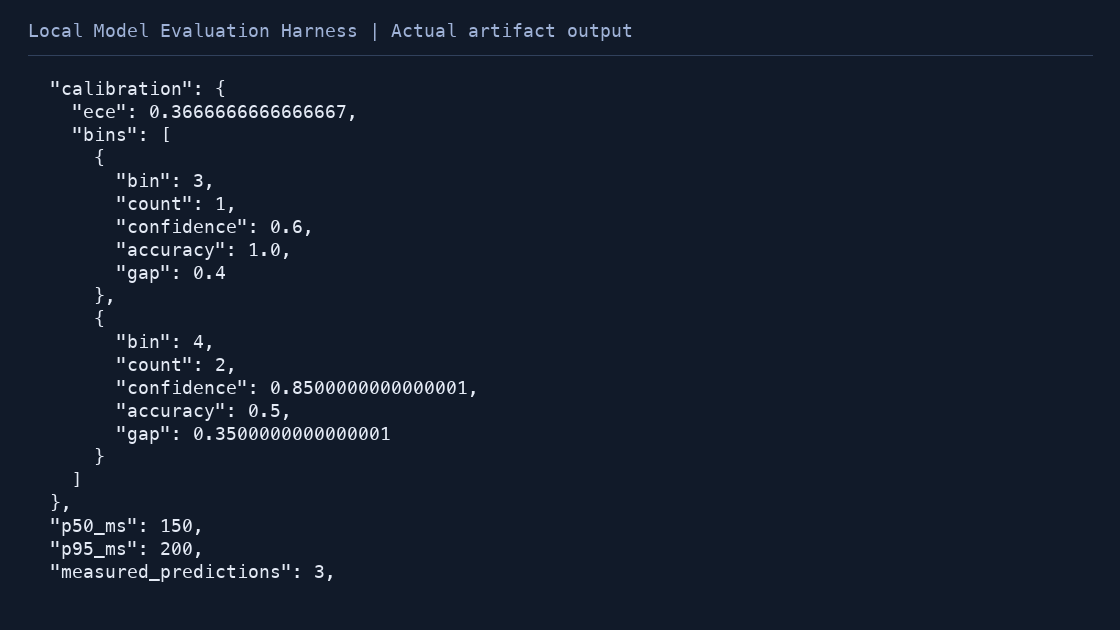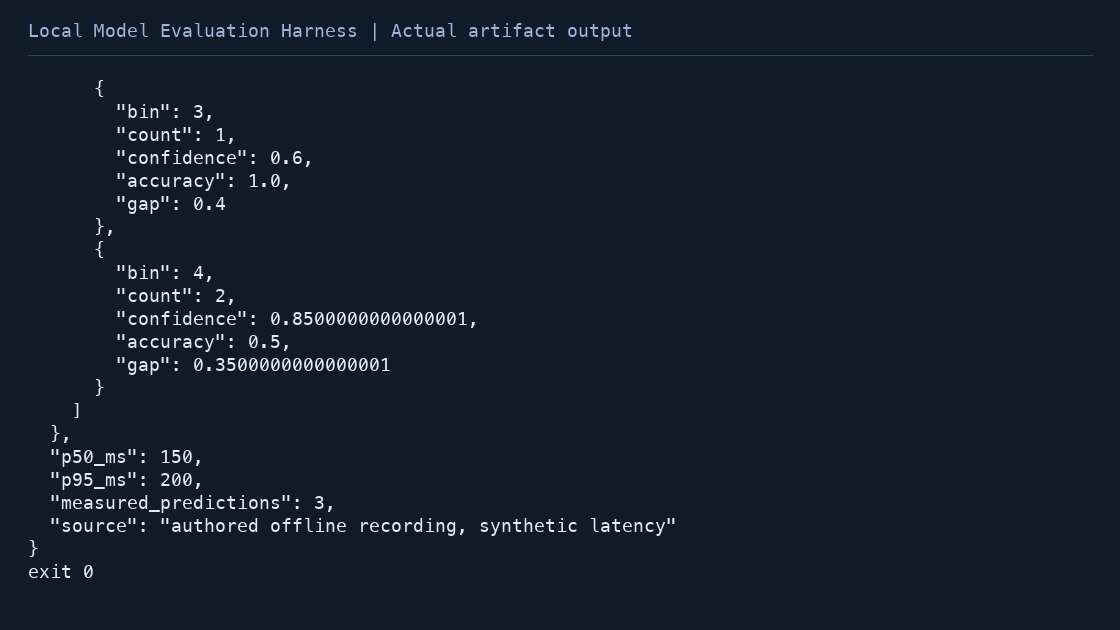
python3 cli.py samples/input.json --output scorecard.json --html reliability.html
The driver and offline samples are provided scaffolding. Its imports resolve to your implementation. Public input types and function signatures live in the starter and API contract.
Inspect the reference separately
From the repository root:
python3 scripts/project_test.py local-model-eval-harness --all --solution --strict
cd projects/local-model-eval-harness/solution
python3 cli.py samples/input.json --output scorecard.json --html reliability.html
Observe the change
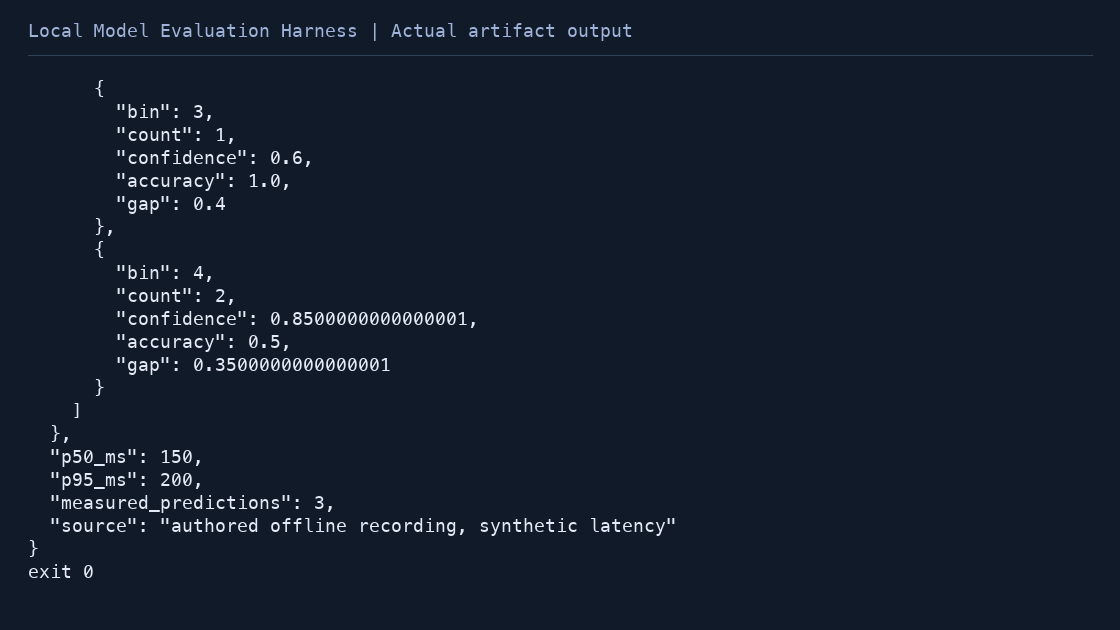
The supplied three predictions score 2/3 accuracy with full coverage. Its p95 is200 ms from an explicitly synthetic recording. record.py measures elapsed time for actual loopback calls and captures the execution manifest.
Edit a copy of the sample and rerun the command. Keep the input beside the output so someone else can reproduce the result; the supplied samples are authored teaching data.
Integration and limits
record.py writes the same {manifest,source,labels,records} contract consumed by cli.py. --baseline compares only identical label fingerprints; --min-accuracy supplies a local CI gate.
Reported confidence is model self-report unless your adapter defines another method. ECE varies with bins and sample count. No model is downloaded or started, and the sample is not a hardware benchmark.
To record an already-running local server, run from the completed workspace:
python3 record.py samples/cases.json --endpoint http://127.0.0.1:11434/v1/chat/completions --model YOUR_INSTALLED_MODEL --revision YOUR_MODEL_REVISION --hardware YOUR_HARDWARE --output measured.json
python3 cli.py measured.json --baseline samples/input.json --output compared.json
The comparison command intentionally rejects different dataset labels. Compare against a prior recording of the same cases when evaluating a model change.
Stages
- Validate prediction records
- Measure normalized exact-answer accuracy
- Measure confidence calibration
- Publish accuracy and latency together
Primary references
Read portable recordings
Use --predictions predictions.jsonl --labels labels.jsonl --manifest manifest.json instead of the single input file. Prediction rows contain id, answer, confidence and latency_ms. Label rows contain id and expected; the manifest contains model, model_revision, prompt_revision, hardware and confidence_method.
Add --dataset-audit /path/split-audit.json to require the Dataset Split Auditor's usable receipt and matching test ids. The returned dataset_audit_sha256 records which audit was consumed. Labels and predictions can change independently, so both checks matter.